Tasks and threads
CUDA.jl can be used with Julia tasks and threads, offering a convenient way to work with multiple devices, or to perform independent computations that may execute concurrently on the GPU.
Task-based programming
Each Julia task gets its own local CUDA execution environment, with its own stream, library handles, and active device selection. That makes it easy to use one task per device, or to use tasks for independent operations that can be overlapped. At the same time, it's important to take care when sharing data between tasks.
For example, let's take some dummy expensive computation and execute it from two tasks:
# an expensive computation
function compute(a, b)
    c = a * b             # library call
    broadcast!(sin, c, c) # Julia kernel
    c
end

function run(a, b)
    results = Vector{Any}(undef, 2)

    # computation
    @sync begin
        @async begin
            results[1] = Array(compute(a,b))
            nothing # JuliaLang/julia#40626
        end
        @async begin
            results[2] = Array(compute(a,b))
            nothing # JuliaLang/julia#40626
        end
    end

    # comparison
    results[1] == results[2]
end
We use familiar Julia constructs to create two tasks and re-synchronize afterwards (@async and @sync), while the dummy compute function demonstrates both the use of a library (matrix multiplication uses CUBLAS) and a native Julia kernel. The function is passed three GPU arrays filled with random numbers:
function main(N=1024)
    a = CUDA.rand(N,N)
    b = CUDA.rand(N,N)
    run(a, b)
end
The arrays are initialized on the stream of the main task, and used from the streams of the two tasks that run spawns. GPU operations execute asynchronously, so that initialization may not have finished when the tasks start. CUDA.jl takes care of that: it remembers which stream last used each array, and orders work on the array from another stream after all the work that was queued on that stream before:
- for operations that CUDA.jl submits itself, i.e., kernel launches (including broadcasts and KernelAbstractions kernels), copies,
fill!and graph launches, the new stream waits for the previous one on the GPU, without blocking the task; - for other uses of the array's memory, like library calls (the matrix multiplication in
computeuses CUBLAS) or passing a pointer to C code or MPI, the task first waits until the previous stream has finished its work, because CUDA.jl doesn't know which stream, or whether the CPU, will access the memory.
Unified and host memory, and memory that is used on another device, are always waited for by the task.
Using Nsight Systems, we can visualize the execution of this example:
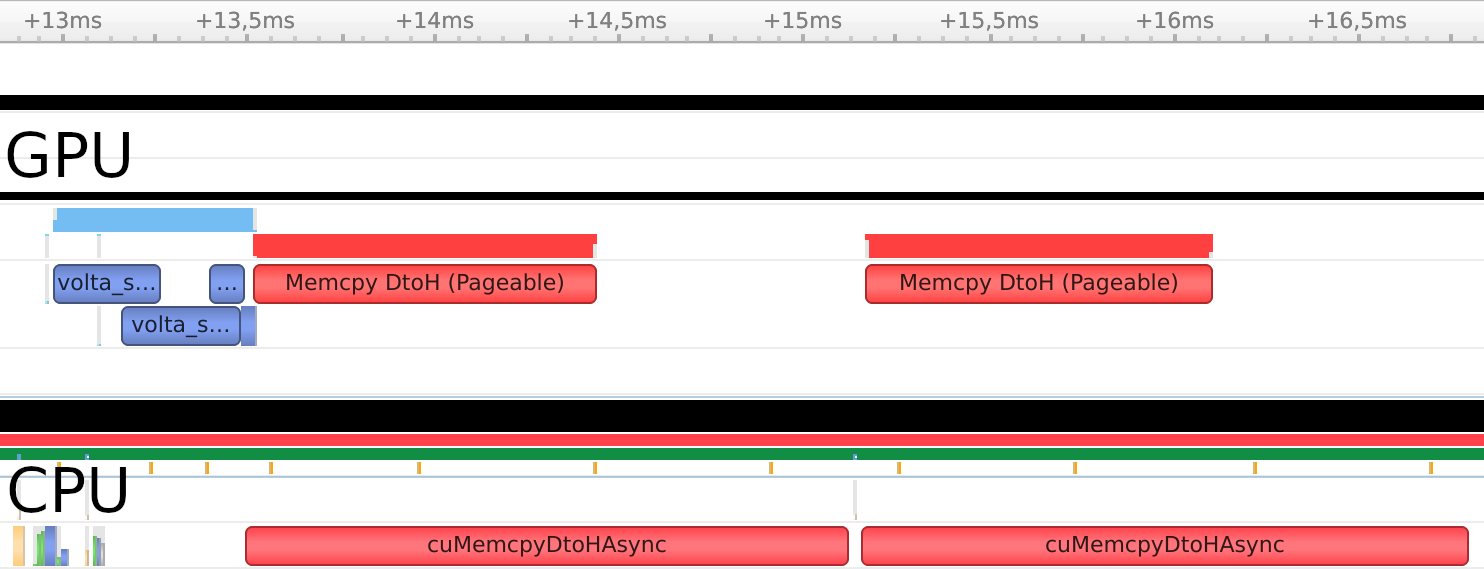
You can see how the two invocations of compute resulted in overlapping execution. The memory copies, however, were executed in serial. This is expected: Regular CPU arrays cannot be used for asynchronous operations, because their memory is not page-locked. For most applications, this does not matter as the time to compute will typically be much larger than the time to copy memory.
If your application needs to perform many copies between the CPU and GPU, it might be beneficial to "pin" the CPU memory so that asynchronous memory copies are possible. This operation is expensive though, and should only be used if you can pre-allocate and re-use your CPU buffers. Applied to the previous example:
function run(a, b)
    results = Vector{Any}(undef, 2)

    # pre-allocate and pin destination CPU memory
    results[1] = CUDA.pin(Array{eltype(a)}(undef, size(a)))
    results[2] = CUDA.pin(Array{eltype(a)}(undef, size(a)))

    # computation
    @sync begin
        @async begin
            copyto!(results[1], compute(a,b))
            nothing # JuliaLang/julia#40626
        end
        @async begin
            copyto!(results[2], compute(a,b))
            nothing # JuliaLang/julia#40626
        end
    end

    # comparison
    results[1] == results[2]
end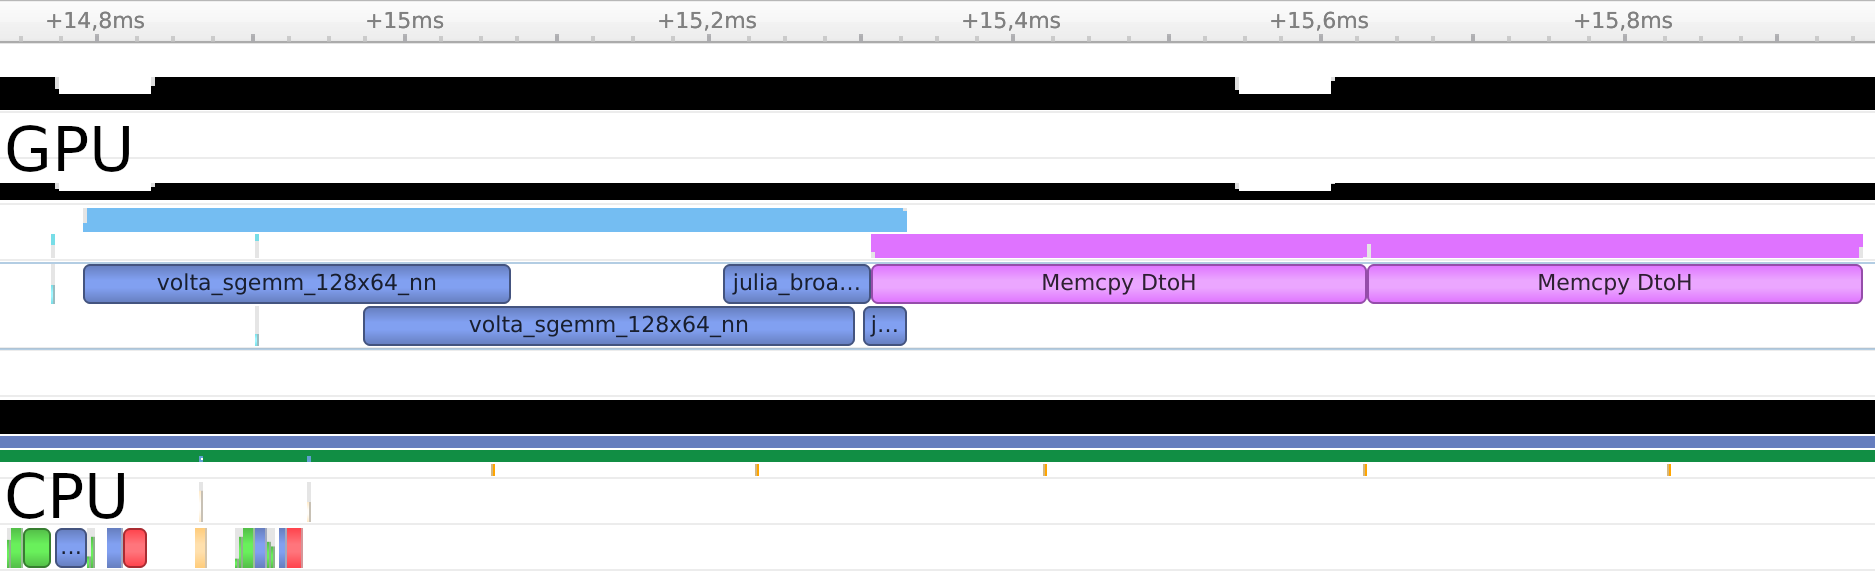
The profile reveals that the memory copies themselves could not be overlapped, but the first copy was executed while the GPU was still active with the second round of computations. Furthermore, the copies executed much quicker – if the memory were unpinned, it would first have to be staged to a pinned CPU buffer anyway.
Streams are not free: each one holds on to some device memory, and many streams slow down memory allocation. To keep applications that spawn many short-lived tasks from accumulating streams, the stream of a task is recycled once the task has finished and all work on it has completed. Tasks that are running at the same time never share a stream, but a newly started task may get the stream of an earlier one. If you need a stream that outlives the task that uses it, e.g., to pass it on to other tasks, create one explicitly with CuStream() and activate it with stream!.
To give a task's subsequent GPU work higher scheduling priority, call CUDA.priority! in that task. For example, CUDA.priority!(:high) selects a high-priority stream; CUDA.priority!(:normal) selects the normal priority again. The scoped form, CUDA.priority!(:high) do ... end, restores the previous stream when the block ends. CUDA treats stream priority as a scheduling hint for pending kernels, and existing work is not interrupted. Repeated priority changes reuse the task's streams. Using an array from before the switch then waits for pending work on its previous stream, as described above; for library calls, that blocks the task, so switch before queuing long work when that wait matters. New tasks start at normal priority, even when spawned from a high-priority task. If you selected an explicit stream with stream!, use the scoped form of priority! to restore that stream after the priority change.
When another task uses an array, CUDA.jl makes it wait for the work that was submitted for that array before. That includes work submitted through a pointer to the array's memory, e.g., one obtained with pointer(a) and passed to a library or a kernel, but only if it was submitted from the task that took the pointer, and before the array was used by another task. Work submitted through such a pointer later is not ordered with the other task's work, so take the pointer again instead.
Multithreading
Use of tasks can be easily extended to multiple threads with functionality from the Threads standard library:
function run(a, b)
    results = Vector{Any}(undef, 2)

    # computation
    @sync begin
        Threads.@spawn begin
            results[1] = Array(compute(a,b))
            nothing # JuliaLang/julia#40626
        end
        Threads.@spawn begin
            results[2] = Array(compute(a,b))
            nothing # JuliaLang/julia#40626
        end
    end

    # comparison
    results[1] == results[2]
end
By using the Threads.@spawn macro, the tasks will be scheduled to be run on different CPU threads. This can be useful when you are calling a lot of operations that "block" in CUDA, e.g., memory copies to or from unpinned memory. The same result will occur when using a Threads.@threads for ... end block. Generally, though, operations that synchronize GPU execution (including the call to synchronize itself) are implemented in a way that they yield back to the Julia scheduler, to enable concurrent execution without requiring the use of different CPU threads.